SLM vs LLM for Low-Volume AI Agents: How to Get an AI Bill You Can Budget
The short answer: for a low-volume AI agent or voice agent, a commercial large language model (LLM) can cost very little, but you can’t know the bill in advance. A small language model (SLM) on your own cloud server costs a fixed amount, about $150 to $300 a month, whatever the usage. If a predictable budget matters more to you than the last few points of answer quality, the small model usually wins. Our Agent Engineering team helps founders make this call with their own numbers.
Founders rarely tell us AI is too expensive. They tell us they can’t plan for it. A finance team can approve a fixed line in the budget. It struggles to approve a cost that “depends on how much people use it”.
What are the two ways to pay for AI?
A commercial LLM (pay per use). You send each question to a provider such as Anthropic, OpenAI or Google and pay for the text the model reads and writes, counted in tokens (a token is about three-quarters of a word). No servers to run. The bill is roughly:
All three numbers can move. More users, longer conversations, bigger documents pulled into each answer, or a model upgrade with a new price: each one changes the bill.
A small model on your own server (pay per month). You rent one server and run an open-weight small model on it. The bill is the server’s monthly price. It doesn’t matter how many questions are asked, as long as one server can keep up.
How do an SLM and an LLM compare side by side?
| Commercial LLM, pay per use | Small model on a fixed server | |
|---|---|---|
| Monthly cost | Moves with usage | Fixed, about $150–300 on AWS |
| Budgeting | Forecast, then hope | One known line item |
| Answer quality | The best available, especially on hard reasoning | Good for focused jobs on your own documents |
| Setup effort | Lowest | Higher: someone builds and runs the server |
| Data location | Provider’s or your cloud platform’s | Your own server |
| Spend controls | Caps can switch the agent off when hit | No cap needed |
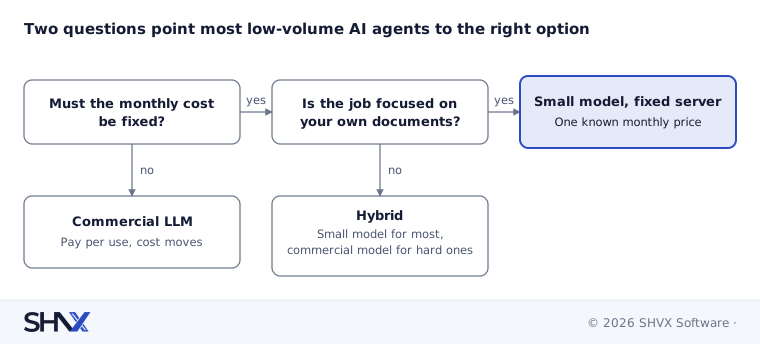
If a fixed monthly cost is a must and the agent answers from your own documents, a small model on one server is usually the right call.
When does pay per use cost less?
At very low volume, a commercial API can cost less than any server. An agent that answers a few hundred short questions a month may cost very little in tokens. If that is your agent, and it will stay that way, pay per use is fine.
The fixed server wins on three things:
- Predictability. One number for the year. No surprise invoice after a busy month.
- No cut-offs. The usual way to make a pay-per-use bill predictable is a spend cap. A cap protects the budget by switching the agent off when it’s reached, often at the busiest moment. A fixed server needs no cap.
- Growth without a rising bill. As usage grows, a fixed server’s cost per conversation falls, until you need a second server.
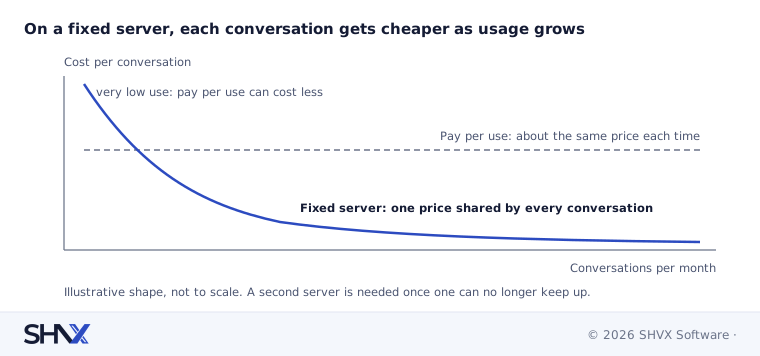
Every extra conversation on a fixed server shares the same monthly price, so the cost of each one keeps falling until the server is full.
What does a fixed server cost?
We ran a small-model AI agent on an everyday 16 GB laptop (see No GPU, No Cloud Bill: An AI Agent That Runs on a Laptop). Comparable servers on AWS, US East region, November 2026:
| AWS server | Good for | Pay as you go, per month | One-year commitment, per month |
|---|---|---|---|
| m7i.xlarge (4 vCPU, 16 GB) | Text AI agent, light use | about $147 | about $103 |
| m7i.2xlarge (8 vCPU, 32 GB) | Text AI agent, more users | about $294 | about $206 |
| g4dn.xlarge (4 vCPU, 16 GB, NVIDIA T4 GPU) | Voice agent, or faster text | about $384 | about $264 |
Server prices only, from public price lists (m7i.xlarge, m7i.2xlarge, g4dn.xlarge). Add storage and data transfer, and check your own region.
Is cloud hybrid RAG worth it at low volume?
RAG (retrieval-augmented generation) means the agent searches your documents before it answers. Hybrid RAG runs two searches, by exact words and by meaning, and merges the results. It is the most reliable way to find the right passage (see our guide to hybrid RAG).
The trap at low volume is the search service, not the AI model. Some managed cloud search services charge a minimum monthly amount even when nobody is searching. For an agent with a few hundred documents and a few thousand questions a month, that fixed search cost can be larger than everything else combined.
The fix is to size the search to the job:
- Small document sets (hundreds to a few thousand pages): run keyword and meaning search inside the same server as the model. Many lightweight libraries and databases do both. No extra service, no extra bill.
- Large or fast-changing document sets, or many users: a managed search service earns its cost. Price it before you design around it.
Hybrid RAG is still worth it. It’s the managed search service that has to earn its place.
When is a commercial LLM the right call?
- The questions need deep reasoning or broad world knowledge.
- Usage is tiny and will stay tiny.
- You have nobody to look after a server, and don’t want a partner to.
- You need the agent live this week, and will revisit cost later.
Many teams end up hybrid: a small model on a fixed server for the everyday questions, with only the hard ones sent to a commercial model. The fixed part stays fixed, and the variable part stays small. For the wider hosting choices, from APIs to your own GPUs, see Commercial vs Open-Source LLMs.
How SHVX can help
Want an AI bill your finance team can approve in one line? An SHVX assessment tests your questions on a small model and a commercial model, sizes the server and the search, and gives you a fixed monthly cost with the math behind it.
Learn more about Agent Engineering.
FAQ
What is the difference between an SLM and an LLM?
Size. A small language model has a few billion parameters and runs on an ordinary server or laptop. A large model is far bigger and usually runs as a paid cloud service.
Is a small model always cheaper?
No. At very low volume a pay-per-use LLM can cost less. The small model’s advantage is a fixed, predictable cost.
Can I make a commercial LLM bill predictable?
Partly, with spend caps and alerts. But a cap protects the budget by stopping the agent when it is reached.
Do I need a vector database for a small AI agent?
Not always. For small document sets, keyword and meaning search can run on the same server as the model.
Server prices checked against public AWS price lists in November 2026. Cloud prices change often; re-check before you budget.